splatt3rs: A Splatoon 3 Automatic Mailbox Message Plotter
While playing Splatoon 3 connected to the network, you can see real players in addition to the offline NPCs. This feature lets the player interact with other players to obtain a copy of their clothes or items. Additionally, players can display messages for others to see. A lot of players include amazing pixel art in their messages, and I wondered how most of them did it, since the process of creating a message is slow and tedious. To display a message, you have to go to the mailbox and input it pixel by pixel with the Joy-Cons, a task which can take hours.
Then I found splork, a tool that translates the pixels of the desired pixel art into controller inputs. It runs on a Raspberry Pi Pico (any RP2040 board) that pretends to be a USB game controller, so the Switch thinks someone is pressing the buttons.
I tried it and it worked, but it was slow because the way it traverses and paints the pixels is very simple and, to be fair, the author lists a faster algorithm in the project's TODO. So I decided to improve it and write it from scratch in Rust, which was also a very good excuse to learn about the USB stack in embedded Rust and to play with complex algorithms. The result is splatt3rs.
splatt3rs has three parts: an optimizer that turns an image into a list of instructions (button presses), a simulator that replays that list into a GIF so I can predict what it will draw, and the firmware for the RP2040 that executes the list.
Analyzing the problem§
The message board is 320×120 pixels. The cursor starts in the top-left corner, one press of the D-pad moves it one pixel, and pressing A paints the pixel under it. The firmware understands nine instructions:
pub enum Op {
    Xp, Xm, Yp, Ym,     // move right, left, down, up
    D,                  // paint the current cell
    XpD, XmD, YpD, YmD, // move, then paint (one button report)
}
The last four are the important ones. A move followed by a paint can be fused into a single instruction, because the controller can hold a direction and A in the same USB report, so it can execute all the instruction set.
For an image with n pixels:
- Every pixel needs at least one instruction (its paint), so
nis a floor. - The floor is achieved only if every pixel can be reached from the previous one with a single step.
- Every extra step through empty cells, or jump between separate regions of pixels, costs an extra step.
To compare algorithms, the ratio between the number of generated instructions and the number of pixels to paint is evaluated. Values between 1.0 and 1.2 are very good solutions, some of them optimal; values over 1.5 have substantial overhead (wasted cursor movements).
How splork solves the problem§
splork sweeps the image line by line (horizontally or vertically, whichever comes out shorter). According to its generator, each pixel of a non-empty line costs two instructions (a paint-or-nothing instruction and a move). Additionally, every line gets 10 extra instructions to compensate cursor drifts. Empty lines are skipped, but a skipped line still costs a move instruction plus the cursor compensation. The instruction count does not depend on how many pixels the image has, only on how many lines are empty. It sends one instruction every 25 ms, so a paint followed by a move gives A button a 25 ms press and a 25 ms release, and then the directional pad the same. That is 50 ms per pixel, painted or not.
It has a fast instruction rate, but is prone to occasional drift and is slow on sparse images.
The Travelling Salesman Problem§
Given a set of points on a grid, a cursor that starts at a fixed corner, we need to find the shortest path that visits all of them. The path does not need to return to the starting point and can revisit any place. This is exactly the problem we want to solve here, a travelling salesman problem (TSP) with Manhattan distances (an open path with a fixed start).
It is an NP-hard problem in combinatorial optimization, important in theoretical computer science and operations research. Deciding whether a perfect plan exists is a Hamiltonian path question on a grid graph, an NP-complete problem.
With up to 38,400 pixels an optimal solution is out of reach in reasonable time, so the plan is to build good heuristics instead of an optimal solver, and to measure how far from the floor they land.
Writing a solver with multiple heuristics§
The optimizer runs four algorithms and keeps the shortest result. They are listed in order of increasing effort:
-
linesweeps columns or rows in order, each line in whichever direction starts closer to the cursor (a snake), and keeps the better of the two orientations. It is fast, but performs poorly on sparse images. -
gridcuts the image's bounding box into square blocks (sizes 2, 3, 4, 5, 6, 8, 10, 16, 20, 40 and 120, all tried in parallel), visits the blocks in a serpentine order, and scans each block in the best of 8 orientations for the current cursor position. Blocks keep the cursor local, so it beatsline, but it knows nothing about the shape of the pixels. -
tsp_stablebuilds a path with a Warnsdorff walk (always step to the neighbouring unvisited pixel that has the fewest unvisited neighbours, which avoids stranding pixels in corners) and jumps to the nearest unvisited pixel when it is stuck. Then it improves the path with local search: 2-opt (reverse a section of the path if that shortens it) and Or-opt (move a short segment of up to 3 pixels somewhere better). It is deterministic and fast. -
tsp_optimalimproves on the previous algorithm using iterated local search (ILS). The algorithm kicks the path in search of a better local optimum (swap two small adjacent windows of up to 30 pixels), repairs it with local search, and keeps the result if the path is shorter. It stops afterretriesconsecutive kicks that did not improve the result or after 10 seconds without improvement. Workers run in parallel, one per core, each with its own seed, and the shortest path wins. The search is affordable because only pixels within Manhattan distance two are evaluated. 4 at distance one plus 8 at distance two gives the 12 nearest neighbours.
Results§
The optimizer was tested against the reference input set, seven 320×120 images. The numbers are the ratio defined above, so 1.000 is perfect and lower is better. The last column is the algorithm that won.
| Image | Pixels | line | grid | tsp_stable | tsp_optimal | Winner |
|---|---|---|---|---|---|---|
| full | 38,400 | 1.000 | 1.000 | 1.000 | 1.000 | any |
| path-fine | 18,880 | 1.971 | 1.089 | 1.000 | 1.000 | tsp |
| graph | 25,840 | 1.199 | 1.035 | 1.002 | 1.001 | tsp_optimal |
| 5start | 9,552 | 1.453 | 1.081 | 1.028 | 1.021 | tsp_optimal |
| mia | 7,499 | 1.364 | 1.230 | 1.116 | 1.078 | tsp_optimal |
| random | 22,401 | 1.695 | 1.361 | 1.265 | 1.183 | tsp_optimal |
| dither | 19,555 | 1.720 | 1.556 | 1.558 | 1.526 | tsp_optimal |
A few things stand out:
lineis never the winner except in ties; images with scattered pixels will always be slow with a simple sweep.- On
path-fine, the cheaptsp_stableis already at 1.000, so the expensive search has nothing left to find. - On
fullevery algorithm is perfect, because a filled rectangle is just thelinealgorithm. - The ILS improves the solution substantially on messy images (
random: 1.265 → 1.183) and gains little on tidy ones. ditheris the hardest case at 1.526. That ratio is not good, but it does not mean it is very far from the optimum; we simply cannot prove it is the best.
After the instruction list is generated, adjacent move and paint instructions are fused into one and the whole list is compressed using a run-length encoding with a variable-width length field.
Simulating the generated instructions§
Before creating the microcontroller firmware I wanted to see how the algorithms would perform. Most pixel art generate very long instruction lists and therefore slow print times.
The simulator replays the instruction list on a blank canvas and either saves the final result (argument -I) or a GIF animation (argument -v). It can also help to debug the algorithm by drawing the cursor's trail in cyan (argument -d). Passing the -f N argument, the animation duration is divided by N.
Let's run the solver on this input image. The image comes from the reference input set, a frame of the game Phoenix Wright: Ace Attorney in which Mia Fey appears in court as the defense attorney.
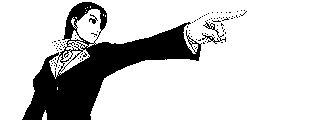
As expected, the tsp_optimal algorithm produces the best result.
In the debug animation we can observe the cursor travelling to the starting point in the image.
This is considered overhead by the ratio metric because it breaks the ideal strategy of never lifting the pencil and never repainting a pixel.
After that, the cursor barely travels without painting anything (which is the desired behavior).
When the animation stops, we can see the very few cyan pixels left.
Deciding whether each of them were truly needed would take vast amounts of computing power, but we can be sure the obtained solution is close to the optimum.
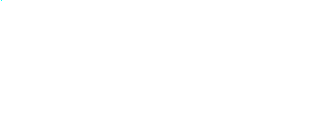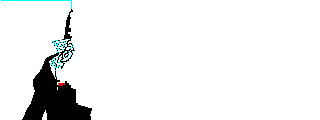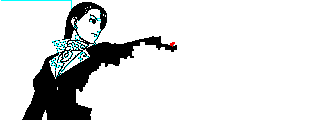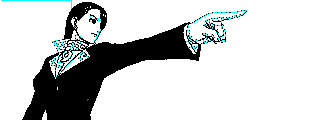
The previous image is a very good candidate for this kind of optimization, but let's run the solver on the image where it performs worst: a dithering pattern.
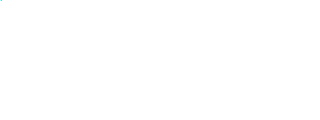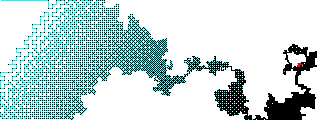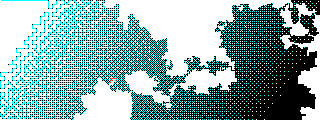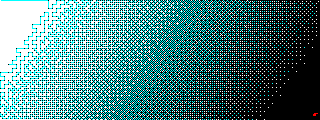
A lot of cyan pixels are still visible in the debug animation, which shows how hard it is for the TSP+ILS variant to shorten the path on this image.
As an additional note, the generated GIFs are very small. Each frame only stores the rectangle that changed, using the "keep" disposal method so everything else stays on screen. A step in which nothing visible changed (for example, a cursor move when debug mode is off) does not create a frame at all; it just extends the delay of the previous one.
Implementing the algorithm in the embedded target: RP2040§
The firmware is also written in Rust on top of the rp-pico board crate and the usb-device / usbd-human-interface-device stack. The Switch only accepts controllers it recognizes, so the board presents itself with the USB identity of a HORI "POKKEN CONTROLLER" (vendor 0x0F0D, product 0x0092), the same trick splork uses.
It implements a small state machine. After a startup delay, it sends a synchronization sequence: L+R presses so the Switch detects the controller, and then A presses to confirm. After that, it moves the cursor to the top-left corner, clears the canvas and then starts executing instructions: one every 64 ms with a 50% duty cycle (press-release).
Note that the firmware supports fused move-and-paint instructions, so it takes advantage of every fusion the solver finds.
Storing the instructions§
As previously mentioned, the instruction list is a compressed bit stream of tokens which contains the instruction data (opcode) and the number of times that instruction must be repeated (run length).
The instruction file starts with a 4-byte header: the letters RLE followed by one byte with the width of the run-length field. The encoder tries every width from 0 to 8 bits and keeps the one that gives the smallest file.
The simulator and the firmware read the header and size their tokens from it (4 bits plus that width).
The unused bits of the last byte are filled with 1s, which read as opcode 15 and tell the decoder to stop.
| Image | Instructions | RLE bits | File size | Compression Ratio |
|---|---|---|---|---|
| mia | 8049 | 1 | 3730 bytes | 92.7% |
| 5start | 9719 | 1 | 4344 bytes | 89.4% |
| dither | 29842 | 0 | 14921 bytes | 100% |
| graph | 25861 | 3 | 8548 bytes | 66.1% |
| path-fine | 18880 | 8 | 227 bytes | 2.4% |
| random | 26465 | 0 | 13233 bytes | 100% |
| full | 38400 | 7 | 880 bytes | 4.6% |
(Instruction counts here are lower than in the following sections because the startup sequence is not stored in the instruction list.)
The compression ratio is the file size, header not included, divided by what the same list would take without run-length encoding, 4 bits per instruction (instructions × 4 bits).
Below 100% the encoding saves space; above 100% it costs space.
In some cases, such as dither and random, the runs are so short that compression does not help at all, so it is better to switch it off and only pack the opcodes.
On the other hand, images with repetitive patterns compress really well, although most images only benefit slightly from this simple scheme.
The worst case is bounded.
A 320×120 canvas has at most 38,400 pixels, so a list never needs more than 2n = 76,800 instructions before fusing.
Because the encoder can always fall back to a width of 0, a plain list at 4 bits per instruction, the file never needs more than 76,800 × 4 bits = 38,400 bytes plus the header. The firmware still allocates a fixed 96 KiB of flash, which is two and a half times what it needs.
Changing the image without recompiling§
The first version of this project used include_bytes!, which required a recompile for every new image.
splork solves this by compiling a placeholder array into the firmware and then searching the binary for it and overwriting it.
I liked the idea and moved it into the linker script. memory.x allocates a region of flash memory, INSTRS.
MEMORY {
    BOOT2 : ORIGIN = 0x10000000, LENGTH = 0x100
    FLASH : ORIGIN = 0x10000100, LENGTH = 2048K - 0x100 - 96K
    INSTRS : ORIGIN = 0x101E8000, LENGTH = 96K
    RAM   : ORIGIN = 0x20000000, LENGTH = 256K
}

EXTERN(BOOT2_FIRMWARE)

SECTIONS {
    /* ### Boot loader */
    .boot2 ORIGIN(BOOT2) :
    {
        KEEP(*(.boot2));
    } > BOOT2
} INSERT BEFORE .text;

SECTIONS {
    .instrs ORIGIN(INSTRS) :
    {
        __instrs_start = .;
        LONG(0xFFFFFFFF);
        FILL(0xFFFFFFFF);
        . = ORIGIN(INSTRS) + LENGTH(INSTRS);
        __instrs_end = .;
    } > INSTRS
} INSERT BEFORE .text;
The linker script also creates a .instrs section and fills it with 0xFF, the value of erased flash.
The only caveat is that the instruction list has to be embedded after the firmware is built.
A small Python script, embed_instrs.py, is provided.
It opens the built firmware in ELF format, finds that section, checks it is a loadable segment (flashing tools silently skip anything that isn't), and writes the payload.
The payload consists of a 16-byte section header: a magic number, the payload length, a CRC-32, the instruction count, followed by the instruction list.
At boot, the firmware reads the section header and refuses to start if the section is still erased, the magic is wrong or the CRC does not match, so a half-finished flash cannot send random buttons to the console.
The flashing tool probe-rs programs the patched ELF firmware flawlessly.
python embed_instrs.py target/thumbv6m-none-eabi/release/rp2040-impl instrs.rle -o rp2040-impl.elf
probe-rs run --chip RP2040 rp2040-impl.elf
Alternatively, you can convert the patched ELF to the UF2 format by using the elf2uf2-rs tool, and program the microcontroller by connecting it to a computer and copying the file while it is in BOOTSEL mode.
Comparison and final thoughts§
Fewer instructions do not necessarily mean less time. The two firmware programs do not spend the same time per instruction, and splork's instruction count follows rules of its own.
splatt3rs. The firmware executes one instruction every 64 ms. An instruction can be a move, a paint, or a move fused with a paint, so the print time is simply the number of instructions times 64 ms. In testing, I've managed to set the instruction period down to 48 ms and get good prints, beating splork on any scenario. The problem is that if the console lags a bit, the synchronization is lost. Since the algorithms used to paint don't have any method of resynchronizing, I preferred the safest option that (almost) never introduces artifacts.
splork. The firmware executes one instruction every 25 ms, but each instruction is a single action (a paint or a move), so every pixel of a line takes two instructions. The generator scans the image by rows (H) or by columns (V), whichever gives the shorter list, and the length of that list depends on the empty lines, not on the pixels. It also has a little overhead on each line to sync the cursor.
To be fair, I didn't have any issues when I used splork, but the fact that there is a tool to compare a screenshot of the result with the input image, and the project's README suggests that sometimes a cleanup is needed when the console lags a bit.
Final results§
Anyway, let's compare both firmware programs on the seven reference images:
| Image | splatt3rs Instructions | splatt3rs Total Time | splork Scan Mode | splork Non-empty Lines | splork Instructions | splork Total Time |
|---|---|---|---|---|---|---|
| mia | 8,082 | 8.6 min | V | 222 | 62,257 | 26.0 min |
| 5start | 9,748 | 10.4 min | H | 92 | 62,857 | 26.2 min |
| dither | 29,848 | 31.8 min | V | 292 | 80,457 | 33.5 min |
| graph | 25,871 | 27.6 min | H | 105 | 71,437 | 29.8 min |
| path-fine | 18,880 | 20.1 min | H | 118 | 80,017 | 33.4 min |
| random | 26,499 | 28.3 min | H | 120 | 81,337 | 33.9 min |
| full | 38,400 | 41.0 min | H | 120 | 81,337 | 33.9 min |
(These are estimates computed from the instruction counts and each firmware's period, not stopwatch measurements. I've only measured mia and it matches the estimate.)
splatt3rs is faster on six of the seven images.
The margin is large when the pixels are sparse or clustered: mia takes 8.6 minutes instead of 26 (3 times faster) and path-fine 20.1 instead of 33.4, because splork has to visit every pixel of every non-empty line.
Dense images gain much less: dither goes from 33.5 to 31.8 minutes, graph from 29.8 to 27.6 and random from 33.9 to 28.3, although an optimized path still brings a gain.
The one loss is full, where there is nothing to skip: a completely filled canvas costs splork 50 ms per cell (two 25 ms instructions) and costs me 64 ms (one fused instruction), so splork wins by about 7 minutes, 33.9 against 41.0. (When tuned to 48 ms it beats splork by 2 ms per pixel).
One small detail: splork firmware presses and releases buttons in an interleaved manner which allows a faster instruction rate but limits its complexity, because it is not allowed to press the same button on consecutive instructions. splatt3rs uses a longer instruction period and splits each instruction into a press and release phase, each taking half of the period.
Bonus: finding the limits of the Switch's USB stack§
The best values for the instruction period and USB polling rate were found by trial and error. I added timing counters to the firmware and recorded when the Switch actually fetched each report. The original firmware pushed a report to the USB stack every millisecond. With that, the Switch did not fetch continuously. It took reports for about 8 ms, then ignored the controller for about 8 ms, with a period of exactly 16 ms. A press or release during the quiet half reached the Switch up to 8 ms later, so the game experienced input jitter. The game reads the controller state 60 times per second (every 16.7 ms), so a state that was too short could get lost between two readings.
While trying to fix this jitter, I found that the practical minimum for a press or release was 32 ms.
Then I found that running the firmware's main loop every 3 ms instead of every millisecond changed the Switch's behavior.
It fetched every report within 3 ms and the quiet periods disappeared and so did the UsbError::WouldBlock condition when trying to write any report.
After that fix, the firmware can print at 48 ms per instruction (24 ms held, 24 ms released) with a 3 ms USB polling period.
But it is fragile. A 24 ms state leaves only about 7 ms of margin over the game's 16.7 ms frame. If the game drops even a single frame, a press or a release is never seen, the cursor desyncs and everything painted after that is shifted. So the values I recommend are 64 ms per instruction, 32 ms held and 32 ms released. A 32 ms state tolerates a frame of drift, and every print I made with it came out right.
This is also where splatt3rs differs from splork: splork's 25 ms slots have about the same thin margin as my 48 ms experiment, which is probably why it needs a fix-up pass diffgen.
What is still missing§
It would be really cool to take advantage of the multiple brush sizes that the game offers. I'm sure it would be a nightmare to design and optimize, but I leave it as a challenge for another day, or year...
The code is on GitHub. Thanks to aveao for splork, without which this project would not exist.
Thank you so much for reading, and have a great day.